Rendering guide · 8 min read
HTML to PDF Rendering: What Is Preserved and What Can Change
Understand how HTML structure, CSS, fonts, images, tables, and page flow translate into a portable PDF document.
Published and technically reviewed by the PDFStack Team · October 14, 2026
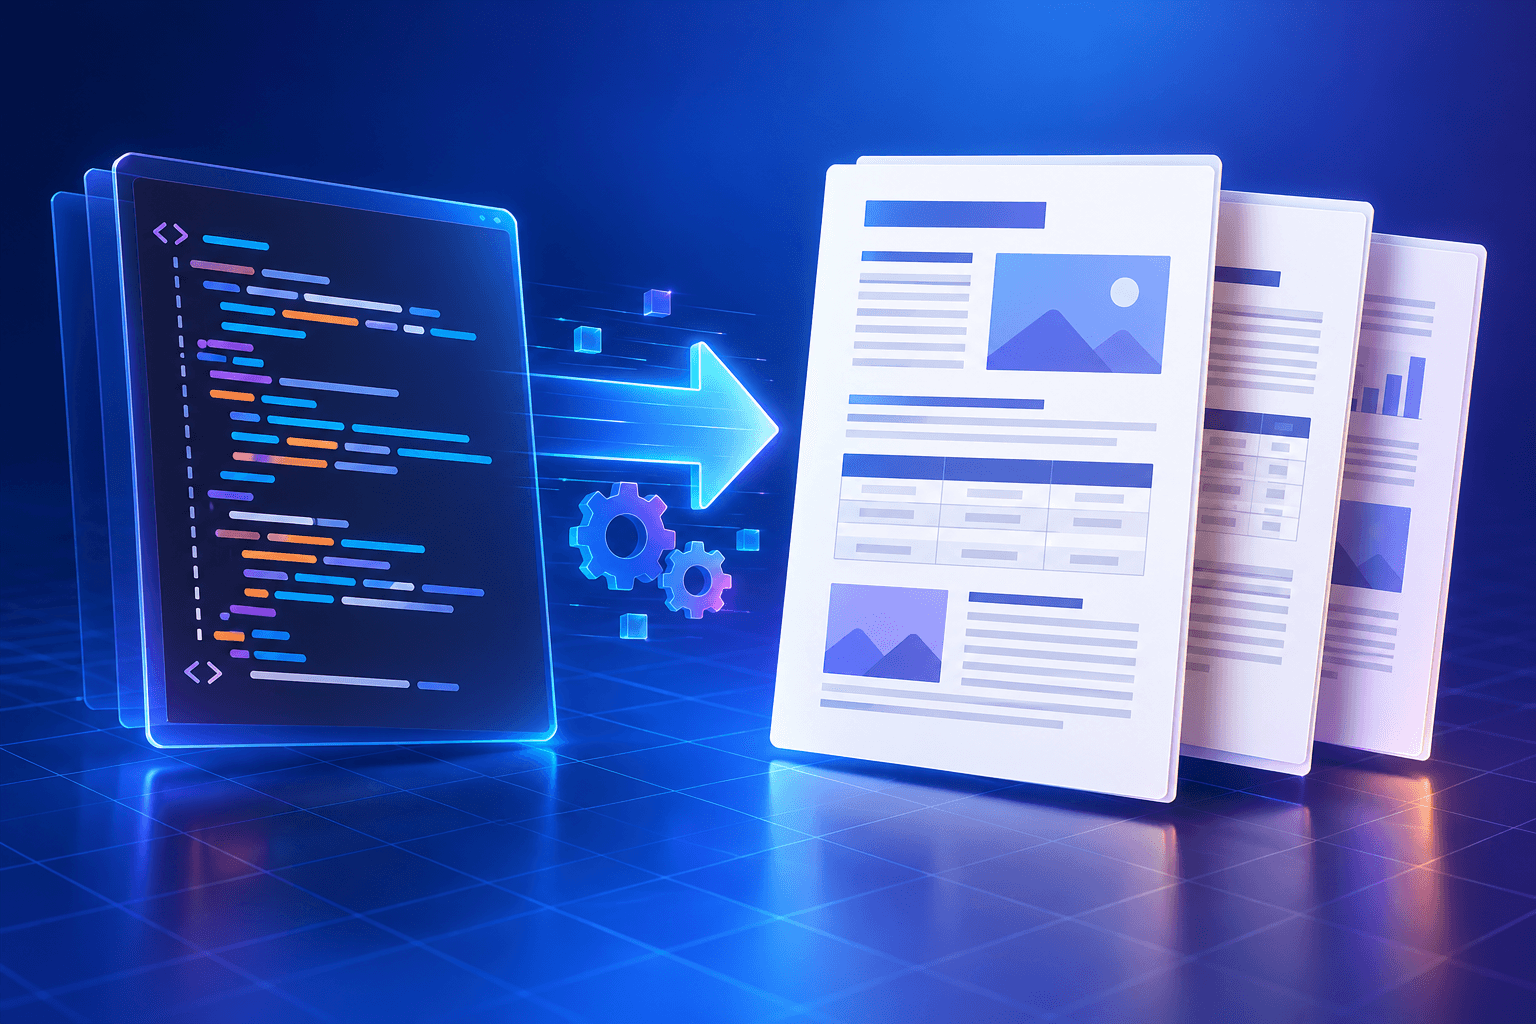
HTML and PDF solve different layout problems
HTML normally adapts to a viewport, available fonts, user preferences, and live browser features. PDF describes fixed pages. Conversion therefore requires decisions about page dimensions, margins, line wrapping, overflow, and where content should break.
A reliable converter should state which structures it understands. Headings, paragraphs, lists, simple tables, blockquotes, and preformatted text can map predictably. Complex application layouts, canvas scenes, video, animation, and script-created content require a managed browser renderer rather than a deterministic text-first engine.
Preserve semantics before decoration
Searchable text, heading order, list content, table rows, and reading sequence are often more valuable than pixel-identical decoration. Rasterizing a webpage can resemble the screen while losing selection, search, links, and accessibility information.
For reports, invoices, documentation, and knowledge-base exports, start with semantic HTML. Keep headings in order, use real lists and tables, and avoid relying on absolute positioning for the main reading flow.
- ✓Use UTF-8 documents.
- ✓Keep important content in semantic elements.
- ✓Embed only resources you are authorized to distribute.
- ✓Inspect page breaks and long tables before sharing.
Fonts and images need explicit handling
A font visible on one computer may not be available on another. A controlled PDF workflow should use known fonts or embed licensed font data. Remote web fonts also introduce network, privacy, and availability dependencies.
Images can be remote, local, embedded, generated by canvas, or protected by authentication. Browser-local conversion should not silently fetch remote resources. If visual fidelity is essential, prepare a self-contained source and verify the exported pages.
Validate the output as a document
Open the PDF, check the first, middle, and final pages, search for known text, and inspect tables or code blocks at normal zoom. Confirm the intended paper size and orientation rather than assuming the browser viewport became the page.
Keep the HTML source as the authoritative editable version. PDF is the distribution output, not a substitute for the source project.
Frequently asked questions
Will HTML and PDF look identical?
Not always. Responsive HTML and fixed PDF pages use different layout models, and unsupported CSS or unavailable resources can change presentation.
Why use text-first conversion?
It preserves searchable text and predictable reading flow instead of turning every page into a screenshot.