Searchable PDFs · 6 min read
Searchable PDF vs Scanned PDF: Why Text Extraction Differs
Understand embedded text, scanned page images, mixed PDFs, and when OCR is the correct next step.
Published and technically reviewed by the PDFStack Team · October 14, 2026
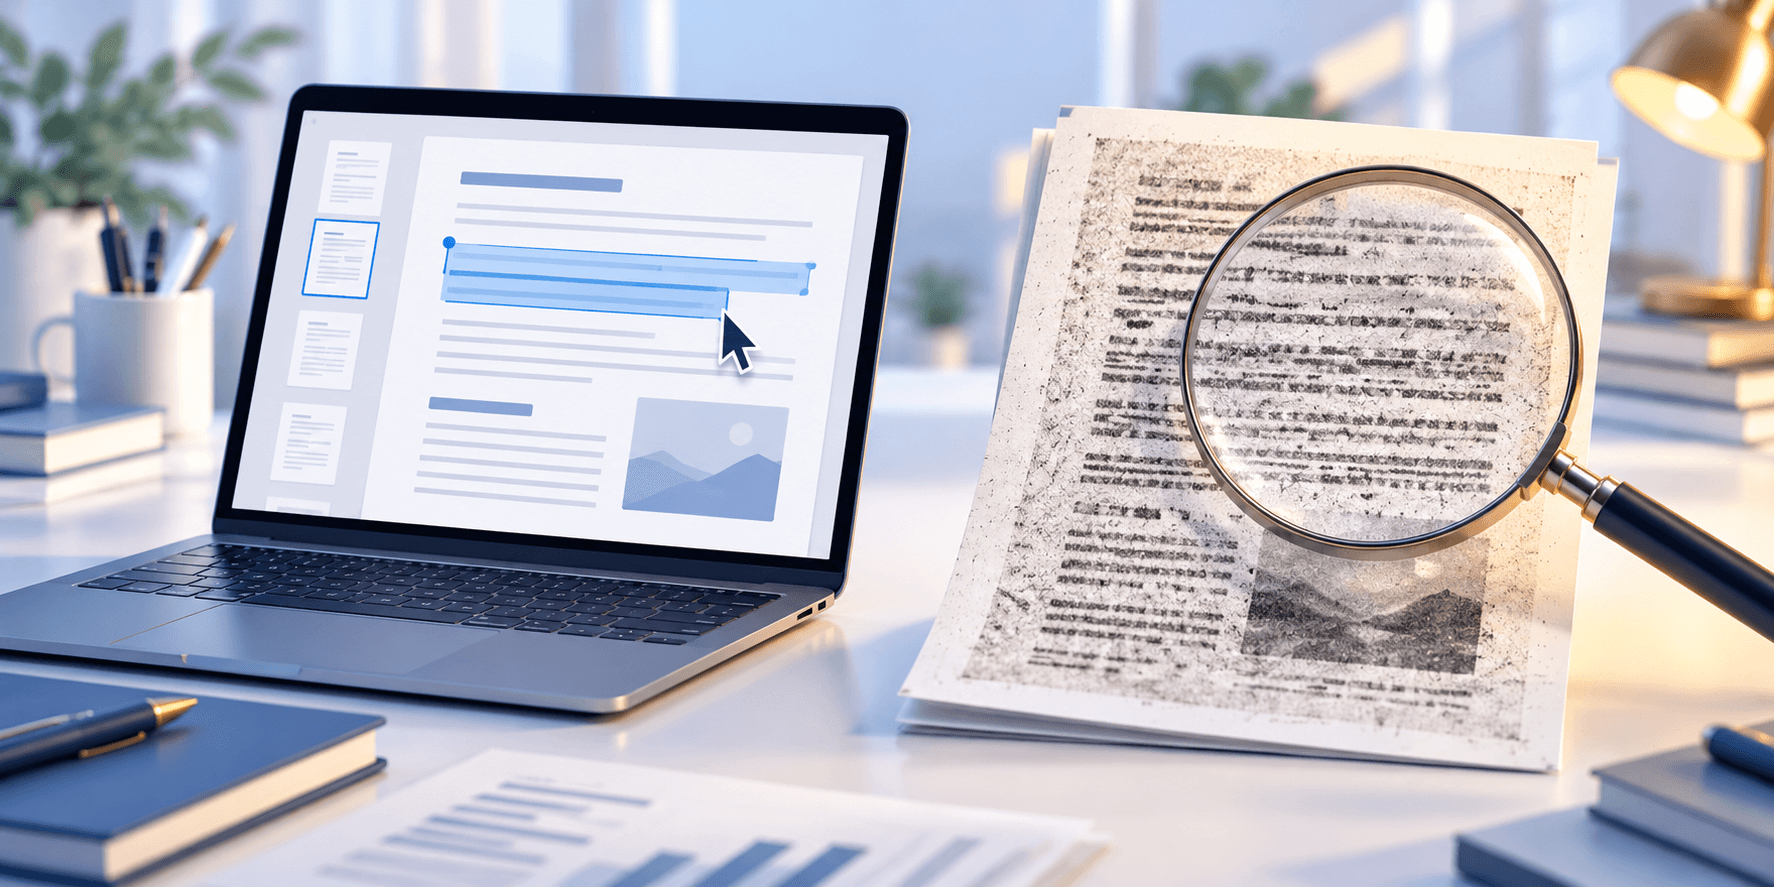
A page can look textual without containing text
A scanner creates an image of a page. Letters remain visible to a person, but the PDF may contain only pixels. A digitally exported PDF usually stores character data that software can select, search, and extract.
Mixed documents are common: a generated cover page may contain text while appended scans contain only images.
How to recognize embedded text
Try selecting individual words, searching for a known phrase, or copying a sentence into a plain-text editor. If selection covers the whole page as one image, the page likely needs OCR.
Some PDFs use unusual character maps. Text may be selectable but copy as incorrect symbols, so the copied result still needs verification.
When OCR is appropriate
OCR analyzes page images and predicts characters. It is the right tool for scans, photographs, and flattened documents, but its accuracy depends on resolution, language, skew, contrast, and typography.
Legal, financial, medical, and archival text should always be checked against the page image after OCR.
Choose the least complex workflow that works
Use direct extraction first for born-digital PDFs because it is faster and does not introduce recognition errors. Move to OCR only for pages that lack usable embedded text.
A clear tool should report empty extraction rather than imply that an image-only page contained no written information.
Frequently asked questions
Can one PDF contain searchable and scanned pages?
Yes. Mixed PDFs are common, so some pages can extract cleanly while others require OCR.
Does OCR guarantee perfect text?
No. OCR is probabilistic and should be reviewed, especially for small type, tables, handwriting, or poor scans.